GoodFit overview
A high-level tour of what GoodFit does, how the system fits together, and the technologies we use.
Product
GoodFit collects and models data on every viable company in the world, plus the key decision makers within them, and turns that into bespoke datasets for clients.
- Data collection. We pull from 30+ sources — some scraped from public sites, some via commercial partnerships.
- Bespoke datasets. Our solutions engineers work with each client to define their sourcing criteria (which companies they care about) and data points (which fields). We build and maintain a dataset tailored to their go-to-market strategy.
- Delivery via CRM. Clients can browse the dataset in the GoodFit app, but most consume it through their CRM. Our integrations layer syncs records into HubSpot / Salesforce, handles record merging, and keeps an audit log of every operation.
- Operationalisation. Once data is in the CRM, clients use it to prioritise accounts, distribute leads, and inform their sales motion.
System overview
See the system board and the more detailed domain map.
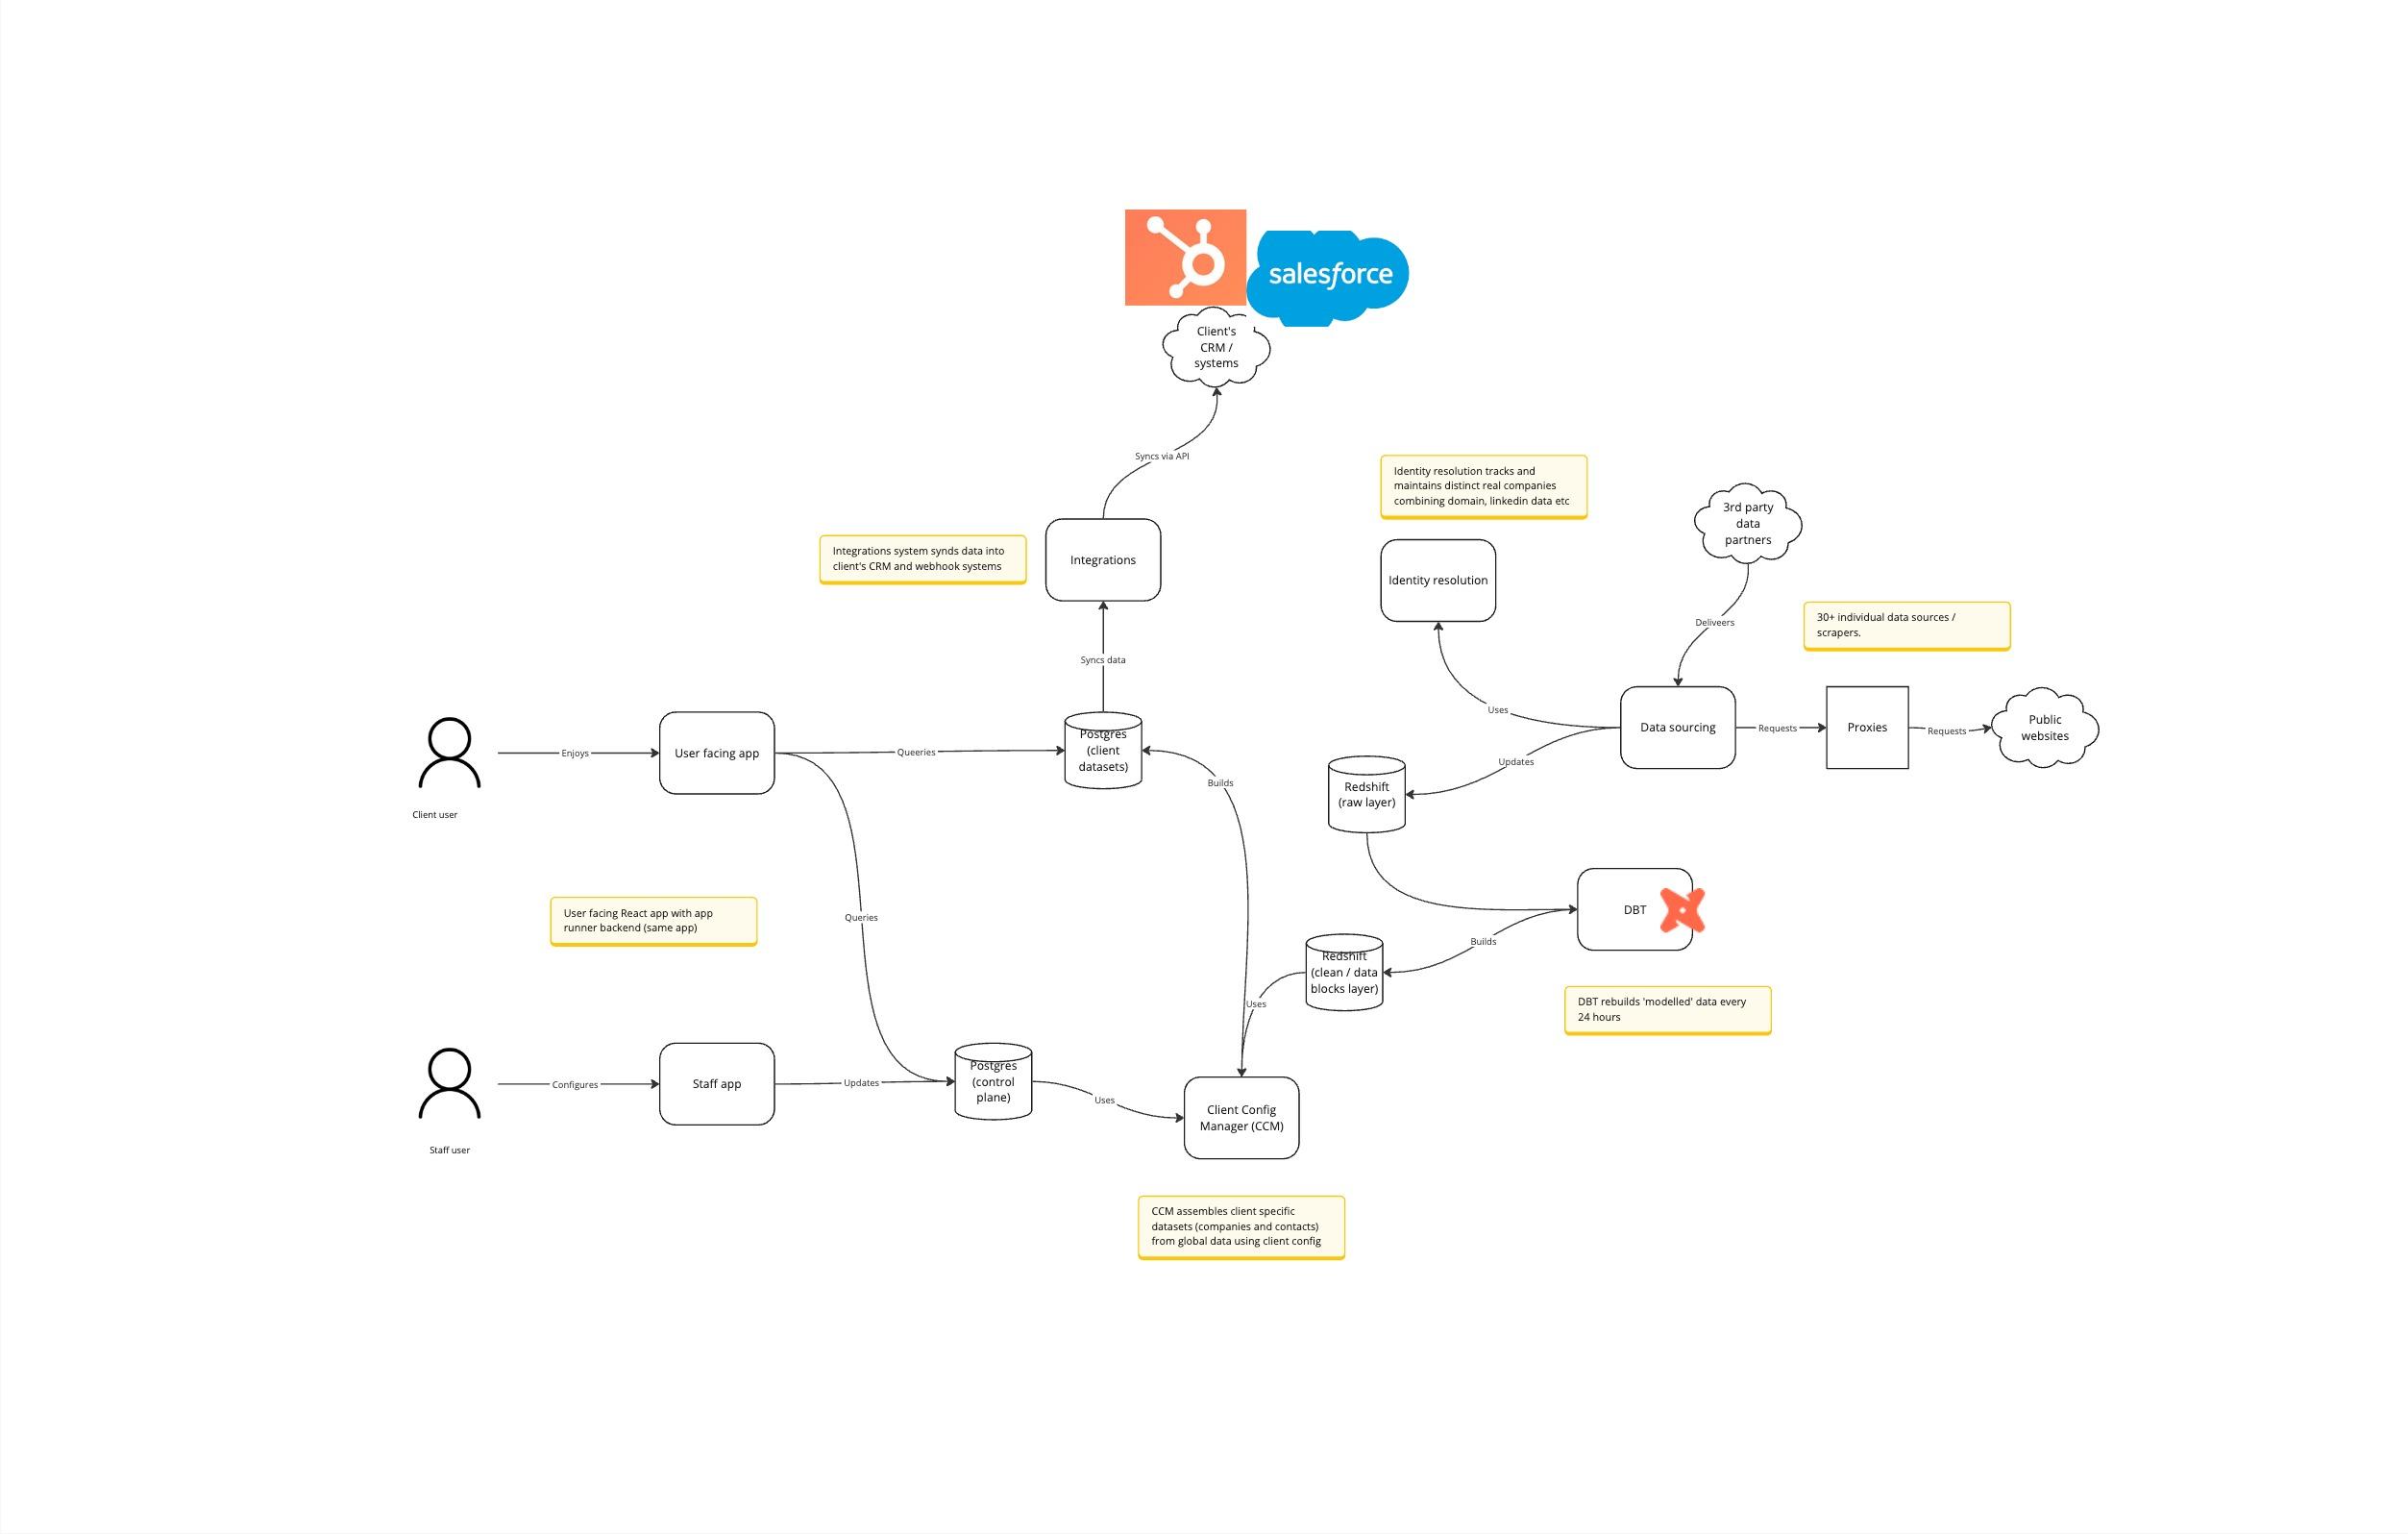
Core pipeline
-
Sourcing. A fleet of AWS Lambdas pulls data from 30+ sources. Scraped sources go through a fleet of proxy providers. Each record has a refresh period that governs how often we re-fetch it; some sources have generators that surface new records as they appear. SLOs monitor refresh rates, and a data-quality system is in development. Collected data lands in Redshift. (diagram)
-
Identity resolution. An identity-resolution service maps incoming identifiers (domain, LinkedIn ID, etc.) onto our internal company schema, accounting for group companies, acquisitions, and similar edge cases.
-
Modelling with DBT. DBT combines and transforms data from multiple sources into data blocks — domain-specific datasets (hiring, team, technology, etc.) all keyed on a normalised company ID. Batch processed every 24 hours.
-
Client config manager. The control plane GoodFit staff use to set and experiment with sourcing criteria and data points. Used heavily during onboarding and throughout the contract as needs evolve. New companies that match a client's criteria are continuously surfaced as we discover them. (diagram)
-
Client app. The bespoke dataset (refreshed daily) is browsable in the client-facing app for preview and exploration. (diagram)
-
CRM sync. Records that have changed in the client's dataset are exported incrementally to S3, then chunked through AWS Step Functions and Lambda to sync into the client's CRM — using batch operations where the CRM supports them. We maintain a mapping from internal record IDs to external IDs so the same record keeps syncing to the same destination. Plenty of edge cases here: 3rd-party errors, rate limits, slow CRMs. Fun times.
Supporting systems
- Email finder. Blends multiple sources and techniques to predict the best email address for a given decision maker. Runs on ECS as a Docker container.
- Crawler. Deep-crawls client sites to detect page elements (e.g. technologies in use) and other context. Some detections (e.g. GraphQL) need a real JS runtime, so we use headless Chromium with Puppeteer on a fleet of ECS-managed EC2 machines.
- Predictive labels. We store embedded webpage text per company. A system lets users train SVM-based classifiers on these vectors to label companies by textual context (B2B vs B2C, ecommerce vertical, type of financial institution, etc.) — predefined industry categories are rarely accurate enough on their own.
Technologies we use
Languages / Code organisation
- Main language is Typescript.
- We use Python when we are dealing with large data processing or machine learning. Pandas (considering Polars), SciKit learn etc.
- We operate a 'semi' monorepo. All backend services live in one repo of multiple deployable services, alongside the main React app (
apps/gf-app), so we can share code and types end-to-end and ship a full feature in a single PR. This repo contains both TS and Python code.- DBT is a separate repo
- See Code & repos for the full list
- We make heavy use of SQL. Not only in DBT for large dataset processing, but also we are not afraid to use SQL in code as opposed to delegating to ORMs. We find ORMs are not good at generating efficient SQL for large datasets. We have a sql template library that allows SQL strings to be assembled using bound parameters, therefore without risk of SQL injection.
Data storage
- We use Postgres for our 'smaller' and 'real time' data. E.g. state that needs quick access or 1:1 row operations. We also store client datasets here as they tend to be small and require low latency access.
- We use Redshift for 'large' data, e.g. on all companies. We store the 'raw' data from sources, and the various layers on top of it, until we end with our 'data blocks' — the cleaned, modelled layer.
- Postgres and Redshift are connected, e.g. we can select data from Redshift from a DBLink query in Postgres, we often use CREATE TABLE AS SELECT FROM dblink for example. We find this to be operationally simple, reliable and faster than exporting via S3.
Infrastructure
- Most systems deploy via the serverless framework (including most that use ECS, using relevant serverless plugins).
- We try to keep individual systems small and deployable quickly (eg each serverless project).
- Most logic is implemented with AWS Lambda functions.
- We use various supporting technologies, e.g. SQS and Step functions to orchestrate work by Lambdas. We can control these via serverless projects.
- In some cases, Lambdas may invoke other Lambdas, but we prefer using SQS or Step Functions to oversee this.
- We don't use Lambdas for user facing APIs, as the start up latency is slow. We use AWS ECS to host an express app in a Docker container instead. This works well. We can control these via serverless projects.
- We use ECS more generally for services where Lambda is not a fit. We can control these via serverless projects.
- Environments are controlled via AWS CDK infra as code. Some older environments include hand built elements, so it's a long term project to unify these and make them all managed by CDK.
Deployment / CICD
- We operate separate AWS accounts for four environments —
dev,dev2,stagandprod. See App Environments. - We use Github actions for CI and CD.
- Upon PR we run all tests (with PG database available with correct schema)
- Deploying to
dev/dev2is via Github action. User selects which service(s) to deploy. - We QA at three points: on
devbefore merging tomain, onstagbefore deploying to production, and onprodafter release to confirm it landed cleanly. See Development Lifecycle.